Pythonで日経平均のWebスクレイピングをやってみた
Pythonにはスクレイピングのためのライブラリが幾つか用意されています。
・urllib(標準ライブラリ)
・requests(https://pypi.org/project/requests/2.7.0/)
・BeautifulSoup(https://pypi.org/project/beautifulsoup4/)
など
ここでは、BeautifulSoupを利用して日経平均株価を取得したいと思います。
日本経済新聞のサイトからデータを取得します。
(2019年11月4日時点ではスクレイピング禁止にはなっていません。)
https://www.nikkei.com/markets/worldidx/chart/nk225/
クローリングによって岡崎市立中央図書館事件のようなことが起こりませんように。。。
このサンプルスクリプトでは、Webサイトにアクセスするのは1回のみのため、大丈夫とは思います。
https://ja.wikipedia.org/wiki/%E5%B2%A1%E5%B4%8E%E5%B8%82%E7%AB%8B%E4%B8%AD%E5%A4%AE%E5%9B%B3%E6%9B%B8%E9%A4%A8%E4%BA%8B%E4%BB%B6
その日の始値、終値、高値、安値などを取得してcsvファイルに保存します。
以下のように保存されます。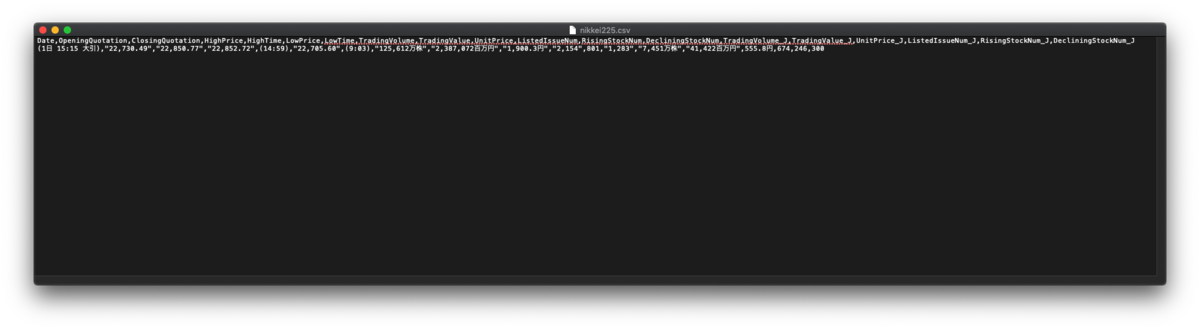
実行したのは以下のコードです。
import urllib.request as urllib2
from bs4 import BeautifulSoup
from datetime import datetime
import csv
import time
import re
import os

def getNikkeiHeikin():
    url = "https://www.nikkei.com/markets/worldidx/chart/nk225/"
    html = urllib2.urlopen(url)
    soup = BeautifulSoup(html, "html.parser")
    allTags = soup.find_all({'th': True, 'td': True, 'tr': True, 'p': True, 'span': True})
    nikkei225 = {}
    flg = False
    for tag in allTags:
        #print(tag)
        if tag.get("class"):
            if tag.get("class")[0] == 'economic_value_time' and re.search("[0-9]+.大引\)$", tag.text):
                nikkei225["date"] = tag.text
                print("Date = " + nikkei225["date"])
            if re.search("^始値", tag.text):
                flg = "始値"
                continue
            if flg == "始値":
                if tag.get("class")[0] == 'm-trend_economic_table_value':
                    nikkei225["openingQuotation"] =  str(tag.text)
                    print("始値 = " + nikkei225["openingQuotation"])
                    flg = False
            if re.search("^高値", tag.text):
                flg = "高値"
                continue
            if flg == "高値":
                if tag.get("class")[0] == 'm-trend_economic_table_value':
                    nikkei225["highPrice"] = tag.text
                    print("高値 = " + nikkei225["highPrice"])
                    flg = False
                elif tag.get("class")[0] == 'm-trend_economic_table_time':
                    nikkei225["highTime"] = tag.text
                    print("高値_時間 = " + nikkei225["highTime"])
            if re.search("^安値", tag.text):
                flg = "安値"
                continue
            if flg == "安値":
                if tag.get("class")[0] == 'm-trend_economic_table_value':
                    nikkei225["lowPrice"] = tag.text
                    print("安値 = " + nikkei225["lowPrice"])
                    flg = False
                elif tag.get("class")[0] == 'm-trend_economic_table_time':
                    nikkei225["lowTime"] = tag.text
                    print("安値_時間 = " + nikkei225["lowTime"])
            if re.search("^年初来高値", tag.text):
                flg = "年初来高値"
                continue
            if flg == "年初来高値":
                if tag.get("class")[0] == 'm-trend_economic_table_value':
                    nikkei225["yearHighPrice"] = tag.text
                    print("年初来高値 = " + nikkei225["yearHighPrice"])
                    flg = False
            if re.search("^年初来安値", tag.text):
                flg = "年初来安値"
                continue
            if flg == "年初来安値":
                if tag.get("class")[0] == 'm-trend_economic_table_value':
                    nikkei225["yearLowPrice"] = tag.text
                    print("年初来安値 = " + nikkei225["yearLowPrice"])
                    flg = False
            if tag.get("class")[0] == 'economic_value_now':
                nikkei225["closingQuotation"] = tag.text
                #print(tag, tag.text, tag.get("class"))
                print("終値 = " + nikkei225["closingQuotation"])
    return nikkei225


def getNikkeiIndex():
    #url = "https://kabutan.jp/stock/kabuka?code=0000"
    url = "https://www.nikkei.com/markets/kabu/japanidx/"
    html = urllib2.urlopen(url)
    soup = BeautifulSoup(html, "html.parser")
    # print(soup.title.string)
    allTags = soup.find_all({'th': True, 'td': True, 'tr': True, 'p': True, 'span': True})
    nikkei225_index = {}
    flg = False
    i = 0
    for tag in allTags:
        #print(tag)
        if re.search("^売買高$", tag.text):
            flg = "売買高"
            nikkei225_index["tradingVolume"] = []  # ["東証一部", "東証二部", "ジャスダック"]
            continue
        if flg == "売買高":
            nikkei225_index["tradingVolume"].append(tag.text)
            i += 1
            if i == 3:
                print("売買高 = " + str(nikkei225_index["tradingVolume"]))
                flg = False
                i = 0
        if re.search("^売買代金$", tag.text):
            flg = "売買代金"
            nikkei225_index["tradingValue"] = []  # ["東証一部", "東証二部", "ジャスダック"]
            continue
        if flg == "売買代金":
            nikkei225_index["tradingValue"].append(tag.text)
            i += 1
            if i == 3:
                print("売買代金 = " + str(nikkei225_index["tradingValue"]))
                flg = False
                i = 0
        if re.search("^売買単価$", tag.text):
            flg = "売買単価"
            nikkei225_index["unitPrice"] = []  # ["東証一部", "東証二部", "ジャスダック"]
            continue
        if flg == "売買単価":
            nikkei225_index["unitPrice"].append(tag.text)
            i += 1
            if i == 3:
                print("売買単価 = " + str(nikkei225_index["unitPrice"]))
                flg = False
                i = 0
        if re.search("^上場銘柄数$", tag.text):
            flg = "上場銘柄数"
            nikkei225_index["listedIssueNum"] = []  # ["東証一部", "東証二部", "ジャスダック"]
            continue
        if flg == "上場銘柄数":
            nikkei225_index["listedIssueNum"].append(tag.text)
            i += 1
            if i == 3:
                print("上場銘柄数 = " + str(nikkei225_index["listedIssueNum"]))
                flg = False
                i = 0
        if re.search("^値上がり銘柄数$", tag.text):
            flg = "値上がり銘柄数"
            nikkei225_index["risingStockNum"] = []  # ["東証一部", "東証二部", "ジャスダック"]
            continue
        if flg == "値上がり銘柄数":
            nikkei225_index["risingStockNum"].append(tag.text)
            i += 1
            if i == 3:
                print("値上がり銘柄数 = " + str(nikkei225_index["risingStockNum"]))
                flg = False
                i = 0
        if re.search("^値下がり銘柄数$", tag.text):
            flg = "値下がり銘柄数"
            nikkei225_index["decliningStockNum"] = []  # ["東証一部", "東証二部", "ジャスダック"]
            continue
        if flg == "値下がり銘柄数":
            nikkei225_index["decliningStockNum"].append(tag.text)
            i += 1
            if i == 3:
                print("値下がり銘柄数 = " + str(nikkei225_index["decliningStockNum"]))
                flg = False
                i = 0
    return nikkei225_index


def writeCSV_nikkei(nikkei225, nikkei225_index):
    print(nikkei225)
    print(nikkei225_index)
    fieldNames = ['Date', 'OpeningQuotation', 'ClosingQuotation', 'HighPrice', 'HighTime', 'LowPrice', 'LowTime',
                  'TradingVolume', 'TradingValue', 'UnitPrice', 'ListedIssueNum', 'RisingStockNum', 'DecliningStockNum',
                  'TradingVolume_J', 'TradingValue_J', 'UnitPrice_J', 'ListedIssueNum_J', 'RisingStockNum_J', 'DecliningStockNum_J']
    fname = "nikkei225.csv"
    fout = os.path.join(os.getcwd(), "nikkei225_csv", fname)
    if os.path.isfile(fout):
        with open(fout, 'a') as csvFile:
            writer = csv.DictWriter(csvFile, fieldnames=fieldNames, lineterminator='\n')
            try:
                writer.writerow(
                    {'Date': nikkei225["date"],
                     'OpeningQuotation': nikkei225["openingQuotation"],
                     'ClosingQuotation': nikkei225["closingQuotation"],
                     'HighPrice': nikkei225["highPrice"],
                     'HighTime': nikkei225["highTime"],
                     'LowPrice': nikkei225["lowPrice"],
                     'LowTime': nikkei225["lowTime"],
                     'TradingVolume': nikkei225_index["tradingVolume"][0],
                     'TradingValue': nikkei225_index["tradingValue"][0],
                     'UnitPrice': nikkei225_index["unitPrice"][0],
                     'ListedIssueNum': nikkei225_index["listedIssueNum"][0],
                     'RisingStockNum': nikkei225_index["risingStockNum"][0],
                     'DecliningStockNum': nikkei225_index["decliningStockNum"][0],
                     'TradingVolume_J': nikkei225_index["tradingVolume"][2],
                     'TradingValue_J': nikkei225_index["tradingValue"][2],
                     'UnitPrice_J': nikkei225_index["unitPrice"][2],
                     'ListedIssueNum_J': nikkei225_index["listedIssueNum"][2],
                     'RisingStockNum_J': nikkei225_index["risingStockNum"][2],
                     'DecliningStockNum_J': nikkei225_index["decliningStockNum"][2]
                     }
                )
            except:
                print("Error")
    else:
        with open(fout, 'w') as csvFile:
            writer = csv.DictWriter(csvFile, fieldnames=fieldNames, lineterminator='\n')
            writer.writeheader()
            writer.writerow(
                {'Date': nikkei225["date"],
                 'OpeningQuotation': nikkei225["openingQuotation"],
                 'ClosingQuotation': nikkei225["closingQuotation"],
                 'HighPrice': nikkei225["highPrice"],
                 'HighTime': nikkei225["highTime"],
                 'LowPrice': nikkei225["lowPrice"],
                 'LowTime': nikkei225["lowTime"],
                 'TradingVolume': nikkei225_index["tradingVolume"][0],
                 'TradingValue': nikkei225_index["tradingValue"][0],
                 'UnitPrice': nikkei225_index["unitPrice"][0],
                 'ListedIssueNum': nikkei225_index["listedIssueNum"][0],
                 'RisingStockNum': nikkei225_index["risingStockNum"][0],
                 'DecliningStockNum': nikkei225_index["decliningStockNum"][0],
                 'TradingVolume_J': nikkei225_index["tradingVolume"][2],
                 'TradingValue_J': nikkei225_index["tradingValue"][2],
                 'UnitPrice_J': nikkei225_index["unitPrice"][2],
                 'ListedIssueNum_J': nikkei225_index["listedIssueNum"][2],
                 'RisingStockNum_J': nikkei225_index["risingStockNum"][2],
                 'DecliningStockNum_J': nikkei225_index["decliningStockNum"][2]
                 }
            )

if __name__ == '__main__':
    nikkei225 = getNikkeiHeikin()
    nikkei225_index = getNikkeiIndex()
    writeCSV_nikkei(nikkei225, nikkei225_index)
Pythonでシェルスクリプトを実行
外部マクロをPythonのサブプロセスで実行した時のメモを残します。
Pythonで外部スクリプトを実行する際、「subscript.call()」関数を用いました。
ここでは、外部マクロをマルチプロセス で動かしたかったので「Process」クラスを利用しました。
from multiprocessing import Process
import subprocess


def f1():
    script = subprocess.call(['bash', './shellscripts/while_1.bash'])
    #print(script)
    print("END")


if __name__ == '__main__':
    p = Process(target=f1)
    p.start()
    print("Process starts...")
subprocess.call()で実行しているwhile_1.bashは2秒おきに0~9の数字をecho文で出力する処理です。
以下のように、Pythonの__main__部分の処理後にsubprocessが始まります。
Process starts...
0
1
2
3
4
5
6
7
8
9
END
【Python】文字列と数字の混在リストのソート
Pythonにはリストの並び替えをする関数が用意されていますが、以下のような文字列に数字が含まれているリストの並び替えでは期待通りの結果を得られませんでした。
lst = ["x2", "x32", "x100", "x13", "x1", "x21"]
sorted(lst)
結果
>> ['x1', 'x100', 'x13', 'x2', 'x21', 'x32']
期待している結果は
>> ['x1', 'x2', 'x13', 'x21', 'x32', 'x100']
やりたいことは「文字列だけれども数値の昇順ソート」です。
そのためには「桁の大きい数値は後ろへ」まわすことが必要です。
そこで、「文字列の長さを比較してから文字列同士を比較」する処理を試します。
def main(lst):
    print("before = ", lst)
    sorted_list = my_sort(lst)
    print("after = ", sorted_list)


def my_sort(lst):
    buf_list = sort_length(lst)
    sorted_list = sort_strings(buf_list)
    return sorted_list


def sort_strings(lst):
    str_sorted = bubble_sort(lst, "strings")
    return str_sorted


def sort_length(lst):
    len_sorted = bubble_sort(lst, "length")
    return len_sorted


def bubble_sort(lst, mode):
    n = len(lst)
    for i in range(n):
        for j in range(n-1, i, -1):
            if mode == 'length':
                if len(lst[j]) < len(lst[j-1]):
                    tmp = lst[j]
                    lst[j] = lst[j-1]
                    lst[j-1] = tmp
            elif mode == 'strings':
                if len(lst[j]) == len(lst[j-1]):
                    if lst[j] < lst[j-1]:
                        tmp = lst[j]
                        lst[j] = lst[j-1]
                        lst[j-1] = tmp
    return lst


if __name__ == '__main__':
    lst = ["x2", "x32", "x100", "x13", "x1", "x21"]
    main(lst)
    lst = ["5", "11", "9", "101", "51", "36"]
    main(lst)
結果は以下のようになりました。
>> before =  ['x2', 'x32', 'x100', 'x13', 'x1', 'x21']
>> after =  ['x1', 'x2', 'x13', 'x21', 'x32', 'x100']
>> before =  ['5', '11', '9', '101', '51', '36']
>> after =  ['5', '9', '11', '36', '51', '101']
今回行った処理は文字列の長さに対してソート(関数:sort_length(lst))してから
文字列の長さが同じ場合に限りソート(関数:sort_strings(lst))をしました。
ソートの手法はバブルソートを用いました。
まとめ
「文字列の長さを比較してから文字列同士を比較」する処理によって数値を含む文字列のソートができました。
マクロの問題点
(1)今回試したマクロではリストの要素に大文字、小文字が混在している場合のソートが上手く働きません。
before =  ['xyz', 'ABC', 'STU', 'abc', 'ghi']
after =  ['ABC', 'STU', 'abc', 'ghi', 'xyz']
['ABC', 'abc', 'ghi', 'STU', 'xyz']とはなりません。
(2)また、ソートの手法にバブルソートを用いているので計算量がO(N^2)となり、長いリストの処理に時間がかかります。
問題(1)、(2)に関しては別の記事で試してみたいと思います。
